Beyond the Chat: Building a Multi-Model AI Interface
How FastApp turns a chat interface into a production-oriented AI layer with dynamic model routing, optional web search, persistent threads, and real-time streaming.
The challenge was not building another chat
A text box connected to a language model can be built quickly. The real challenge begins when that experience must move beyond an isolated demo and become an application people can actually use.
FastApp was built at that point. It connects a conversational interface to different models available through OpenRouter and adds the layers required to turn API calls into a continuous experience: authentication, history, persistence, streaming, and optional tools.
The goal is not to hide every model behind an automatic decision. The user remains in control: they select the model that fits the conversation and decide when web search should be available. The system receives those settings and prepares the agent for that run.
That detail changes the role of the interface. It stops being merely a chatbot screen and becomes an access point for different AI capabilities.
One interface, multiple models
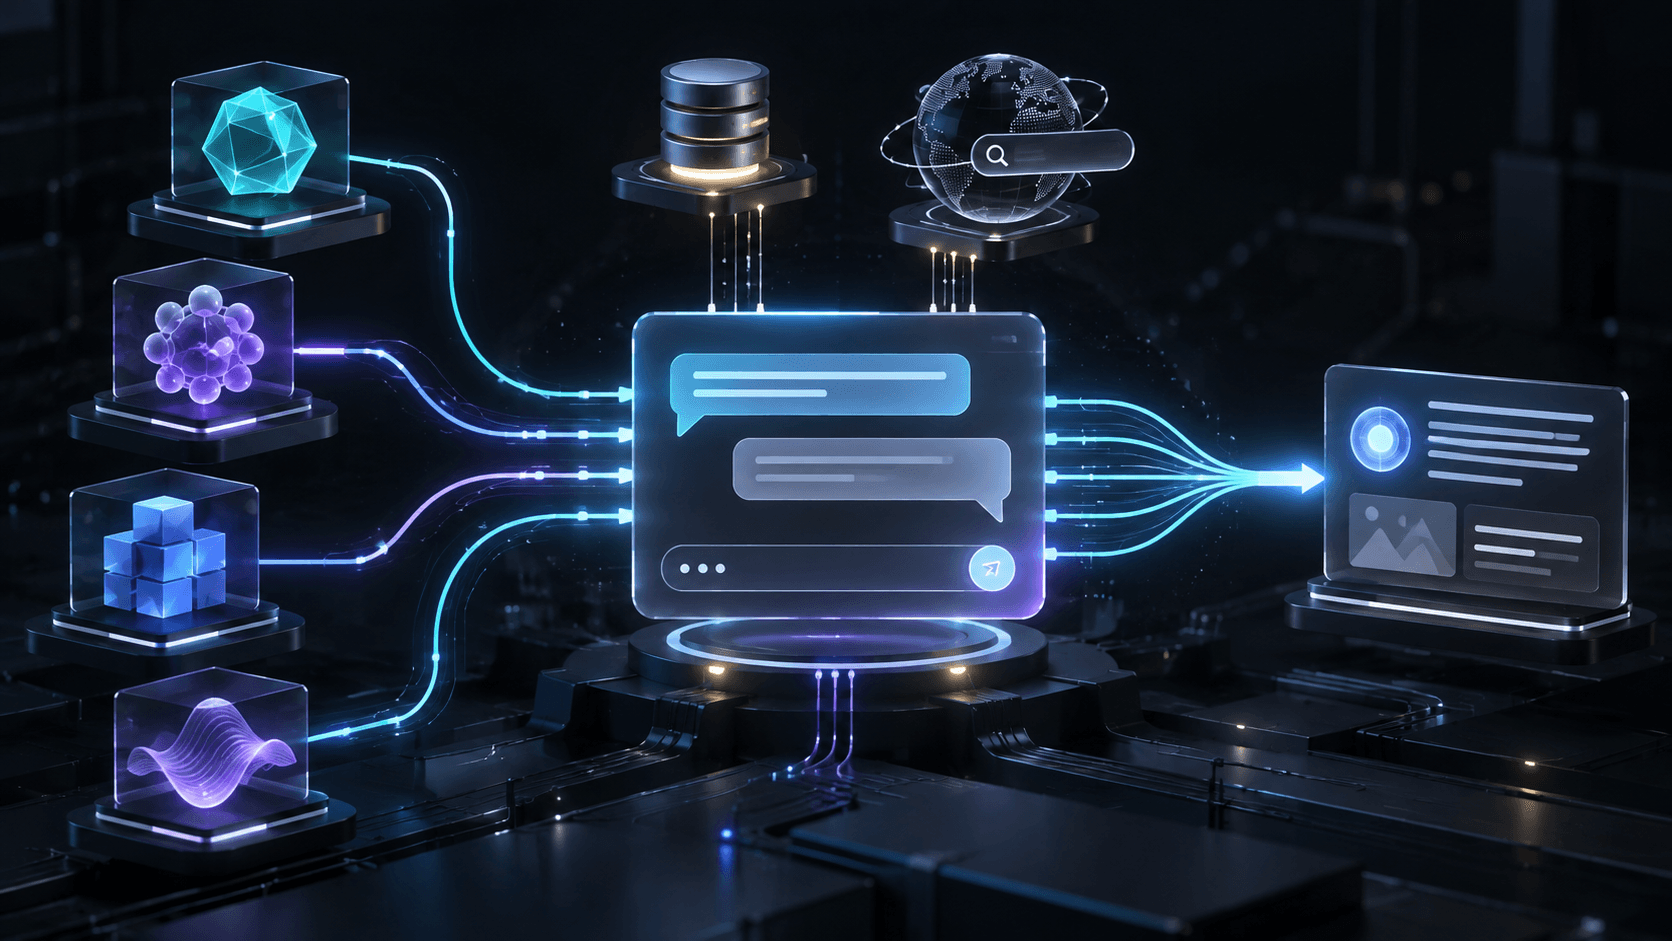
FastApp brings models from different families into a single selector. They are accessed through OpenRouter's OpenAI-compatible layer, reducing the need to implement a separate integration for every provider.
When a message is submitted, the user's choice travels with the run configuration. In the backend, LangChain middleware reads that preference and instantiates the corresponding model for that request.
The flow can be summarized as follows:
- the user selects a model in the interface;
- the frontend sends the message and conversation settings;
- the FastAPI service associates the run with the correct thread;
- the middleware resolves the selected model;
- the agent executes the request through OpenRouter;
- the answer streams progressively back to the interface.
This architecture makes it possible to experiment with models that have different strengths without switching products or losing conversational context. A fast, economical model can handle routine interactions, while a more capable model can be selected when a task requires greater depth.
Tools are part of the configuration
FastApp provides web search through Tavily, but it is not left active for every request. The interface lets the user enable or disable that capability as needed.
In the backend, this decision is more than a text instruction. The middleware filters the tools that are actually available to the agent. When search is disabled, Tavily is removed from the run and an additional guardrail tells the model not to fabricate search results.
This separates two important responsibilities: the model interprets the request, while the application controls which capabilities may be used. The same pattern can be extended to internal APIs, support systems, knowledge bases, or MCP tools.
Streaming changes perceived speed
Waiting for a complete response before displaying it makes any assistant feel slower than it is. FastApp avoids this by using Server-Sent Events (SSE).
The backend observes events produced by the agent and sends each text fragment as soon as it becomes available. The interface updates the answer in real time, creating the progressive writing experience users now expect from modern AI products.
The implementation also protects conversational consistency. The final event is sent only after the run finishes and the updated state can be retrieved from the checkpointer. What appears on screen and what remains stored therefore follow the same lifecycle.
Conversations that survive a refresh
A useful chat needs memory. In FastApp, every conversation receives its own thread, and the agent state is persisted in PostgreSQL through the LangGraph checkpointer.
Alongside the agent checkpoints, a thread table makes recent conversations quick to list. The frontend uses this structure to create conversations, browse history, and resume an earlier interaction.
There is also a summarization layer for long histories. As a conversation grows, middleware retains the latest messages and produces a summary of the earlier context. This reduces what must be sent to the model without treating each new message as an unrelated conversation.
The API as the product boundary
The FastAPI backend does more than relay messages. It defines a clear boundary between the interface and the agent.
This layer exposes endpoints to:
- authenticate access through a passkey and issue an expiring JWT;
- create, list, and retrieve threads;
- execute a synchronous answer;
- stream an answer over SSE;
- report service health.
The OpenRouter key and infrastructure credentials remain on the server. The frontend communicates with the application API rather than directly with AI providers. Configuration, authentication, and persistence are therefore centralized in a layer that can be operated and evolved independently.
From local development to deployment
The project supports two execution paths. During development, the agent can be explored in LangGraph Studio. For a complete deployment, the same logic is exposed through a FastAPI service backed by PostgreSQL, while the Next.js interface is deployed separately.
The backend includes a Docker image prepared for deployment, and the frontend is structured for platforms such as Vercel. This separation allows each side to be scaled and observed according to different needs.
More important than the chosen platforms is the architectural transition: the agent no longer depends on a development interface and instead gains its own API, HTTP contracts, and persistent state.
Deliberate limits of the first version
FastApp is a practical foundation and does not hide its boundaries. Authentication currently uses a shared passkey, which fits a controlled group but does not replace individual accounts, roles, or organization-level isolation.
The model catalog also contains costs configured inside the project; it is not an automatic price-discovery or quality-ranking system. Some combinations of reasoning models and tools also require additional handling for reasoning tokens supplied by the provider.
These limits point clearly to the next layer: per-user identity, usage policies, quotas, cost observability, and more advanced routing rules can be added on top of a foundation that already handles the essential flow.
The main lesson
An LLM hub is not just a list of models. To be useful, it must coordinate selection, context, tools, security, and response delivery as one coherent experience.
FastApp shows how these pieces can work together. Next.js handles interaction, FastAPI establishes the application boundary, LangChain and LangGraph organize the agent and its state, PostgreSQL preserves conversations, and OpenRouter provides a shared doorway to different models.
The result is an interface that can change the engine without rebuilding the car — and a foundation ready for more specialized agents, integrations, and business workflows.